Extract text by table of contents item Leave feedback
On this page
GroupDocs.Parser provides the functionality to extract text by an item of the table of contents. This feature is supported for Word Processing, PDF, ePUB and CHM documents (for more details, see Supported Document Formats).
Text is extracted by the extractText method of the TocItem class:
// Print the text of the chapter
const reader = tocItem.extractText();
try {
  console.log('----');
  console.log(reader.readToEnd());
} finally {
  reader.close();
}
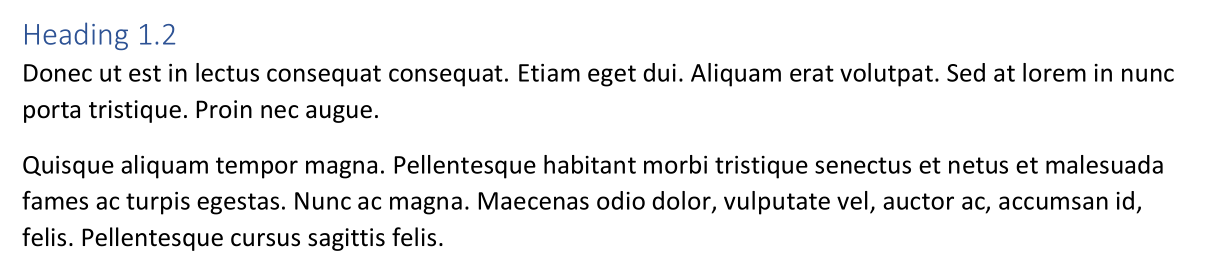
This method returns the text of the chapter to which the table of contents item refers (without sub-chapters). For example, “Heading 1.2” from the page
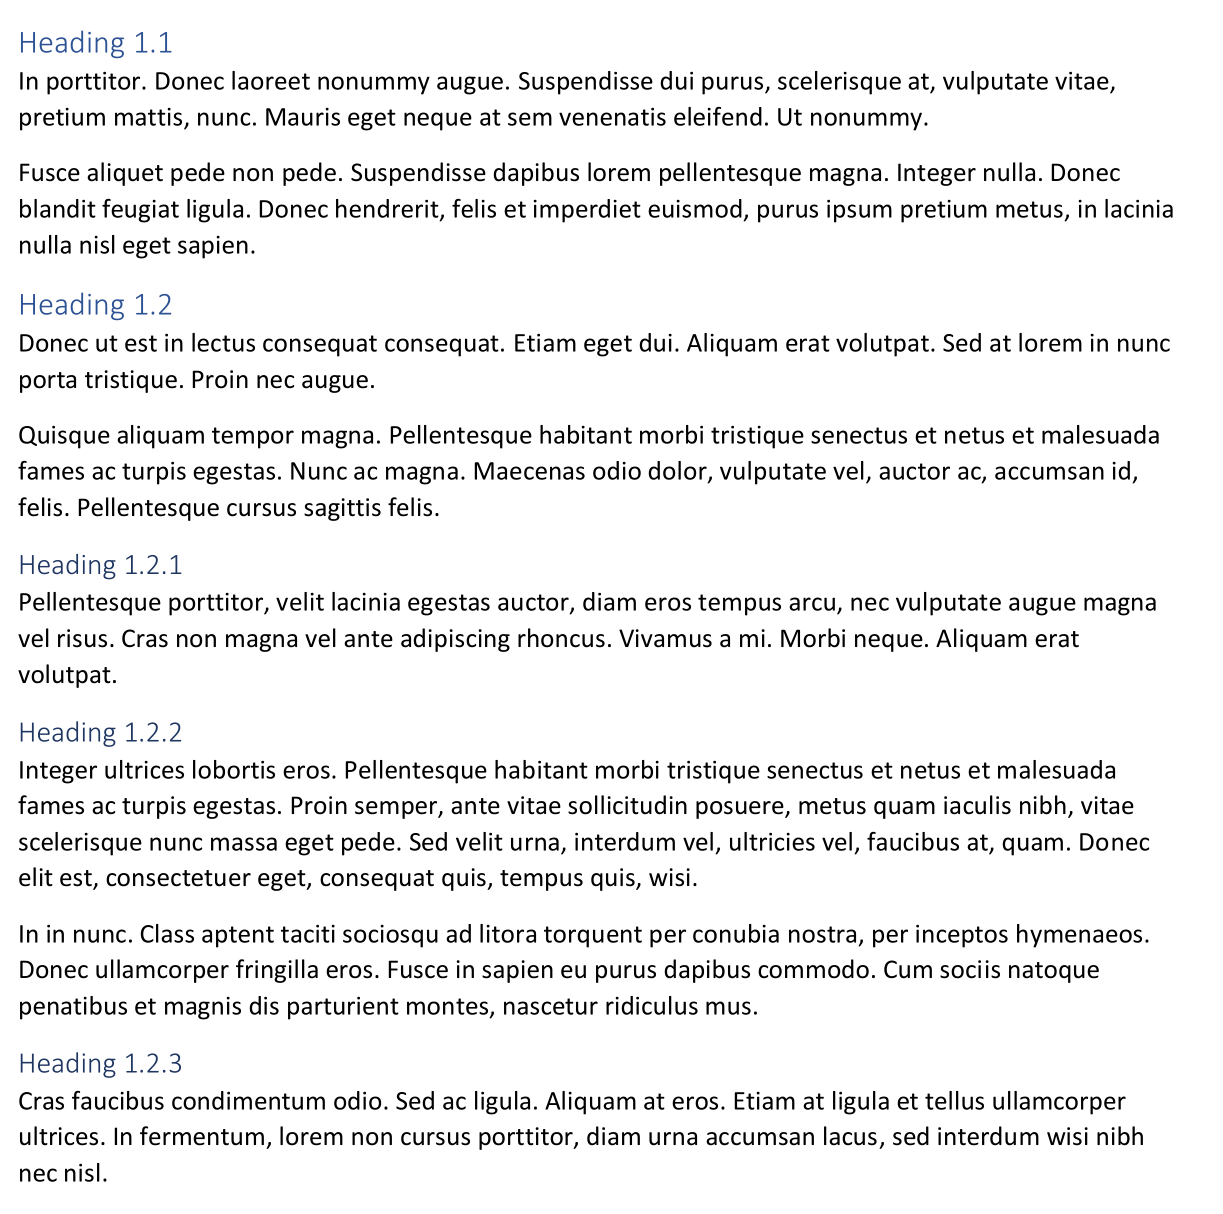
returns the following text:
“Heading 2” from the page:
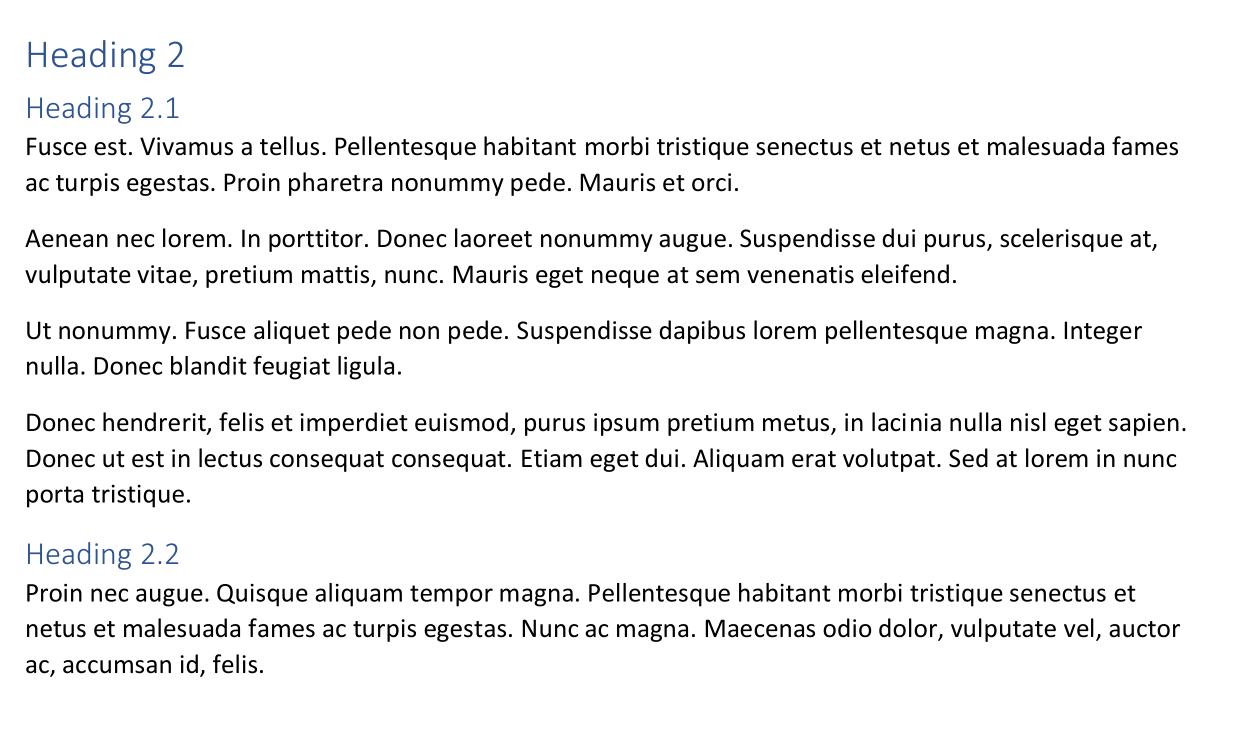
returns the following text:

Warningjava.lang.UnsupportedOperationExceptionis thrown iftocItem.getPageIndex()isnull.
Here are the steps to extract text by an item of the table of contents:
- Instantiate the
Parserobject for the initial document; - Call the
getTocmethod and obtain the collection ofTocItemobjects; - Check if the collection isn’t
null(table of contents extraction is supported for the document); - Iterate through the collection and extract the text.
The following example shows how to extract text by items of the table of contents:
const groupdocs = require('@groupdocs/groupdocs.parser');

// Create an instance of Parser class
const parser = new groupdocs.Parser('SampleWithToc.docx');
try {
  // Get table of contents
  const tocItems = parser.getToc();
  // Check if toc extraction is supported
  if (tocItems == null) {
    console.log("Table of contents extraction isn't supported");
  } else {
    // Iterate over items
    const it = tocItems.iterator();
    while (it.hasNext()) {
      const tocItem = it.next();
      // Print the text of the chapter
      const reader = tocItem.extractText();
      try {
        console.log('----');
        console.log(reader.readToEnd());
      } finally {
        reader.close();
      }
    }
  }
} finally {
  parser.close();
}
process.exit(0);
Along with the full-featured library we provide simple but powerful free apps.
You are welcome to extract data from PDF, DOC, DOCX, PPT, PPTX, XLS, XLSX, Emails and more with our Free Online Document Parser App.
Was this page helpful?
Any additional feedback you'd like to share with us?
Please tell us how we can improve this page.
Thank you for your feedback!
We value your opinion. Your feedback will help us improve our documentation.


